DHM280 · Project 2
How a live stream of tweets became a downloadable monthly dataset, and what a researcher does with it afterwards.
From stream to dataset
- Connect to Twitter’s COVID-19 Streaming Endpoint, which sends every public tweet Twitter tags as being about COVID-19.
- Collect around the clock with the lab’s script. The dashboard even tracks how many tweets came in each hour, which shows any gaps.
- Strip each tweet down to its ID, as Twitter’s rules require.
- Filter out a second, vaccine-only file using keywords.
- Summarize each month on the dashboard.
- Publish both files at the start of the next month.
- Researchers take over: they sample the data with the toolkit, then rehydrate it to get full tweets.
The critical step: the vaccine filter
Most of this process just passes along what Twitter sends. Step 4 is different, because there the lab makes its own call about what counts as a “vaccine tweet.” A tweet goes into the vaccine file if it has a word starting with vaccin*, vacin*, or vax*. The asterisk catches any ending, so it picks up vaccine, vaccinated, vax, vaxxed, and so on. Including “vacin*” also catches a common misspelling, which is a thoughtful touch.
This matters because vaccine misinformation was some of the most harmful content of the pandemic. A ready-made vaccine file lets a communication researcher go straight to that conversation instead of filtering 100 million tweets themselves.
Keyword filters are blunt, though. A tweet about getting “the jab” or “my Pfizer shot” gets missed, and so do tweets written in other languages. Meanwhile, a tweet that mentions vaccines in passing gets pulled in. Anyone using the file needs to know it is a starting point, not a perfect set.
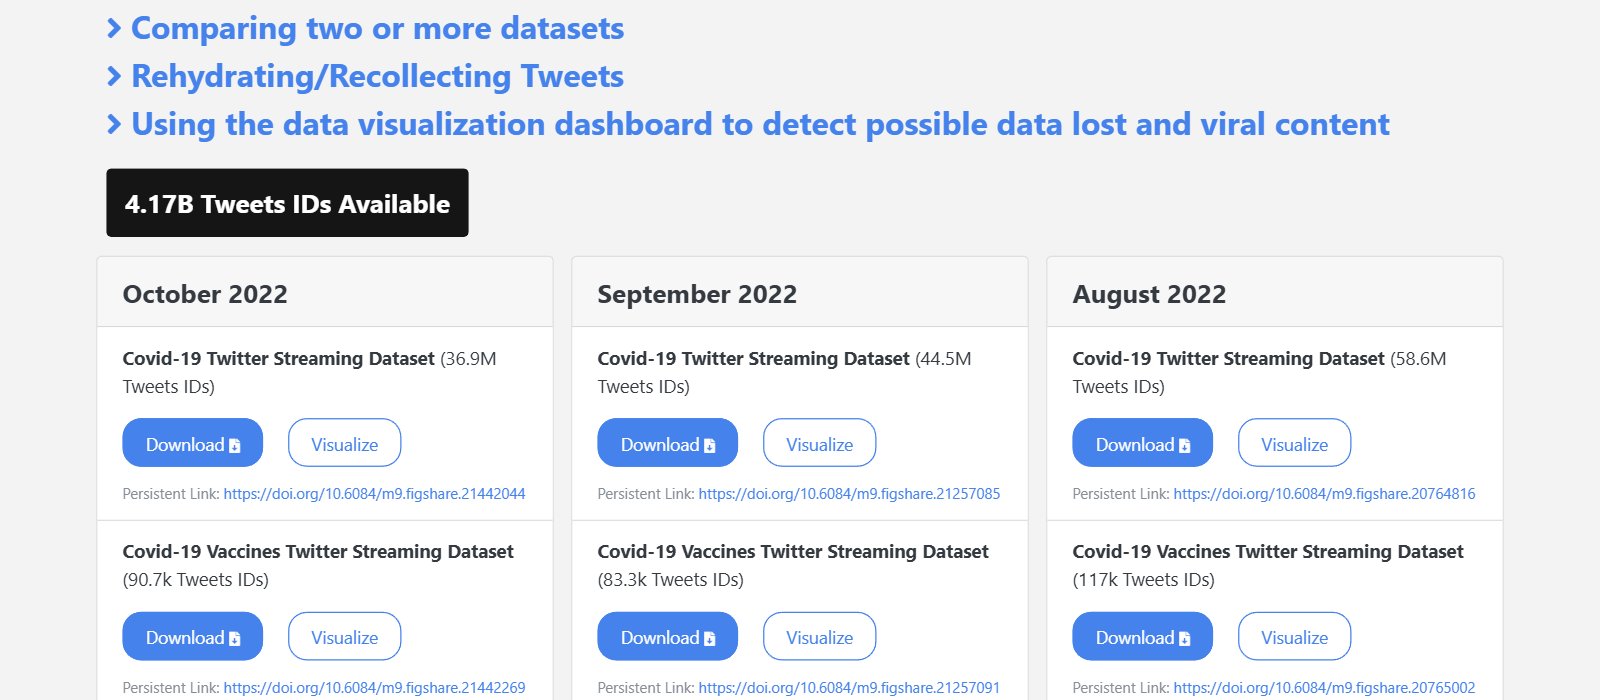
This step happens inside the collection script described on Tools, and it produces the second monthly file described on Data.
How good is the documentation?
For the step the lab controls, it is excellent. The exact keyword rule is written out on the Downloads page, so anyone can understand the vaccine file or repeat the filter on their own data.
Steps 1 and 2 are a different story. They rely on Twitter’s internal rules for what counts as a COVID tweet. The lab points to Twitter’s documentation, but that endpoint is gone now, so this part of the method is a black box the lab never controlled.