The data for this project
The data collected is of key phrases in printed newspapers. It is presented in a database that can be accessed off of their main page.
By having the data in a database, anyone can look up specific words or sentences that would then give them a cluster of papers that match the search.
Input data and sources
The data is collected from already digitized newspapers, mainly from Chronicling America. The digitalization process started around 1980’s and then the Viral Texts Project cleaned it up and put it in a database in 2012.
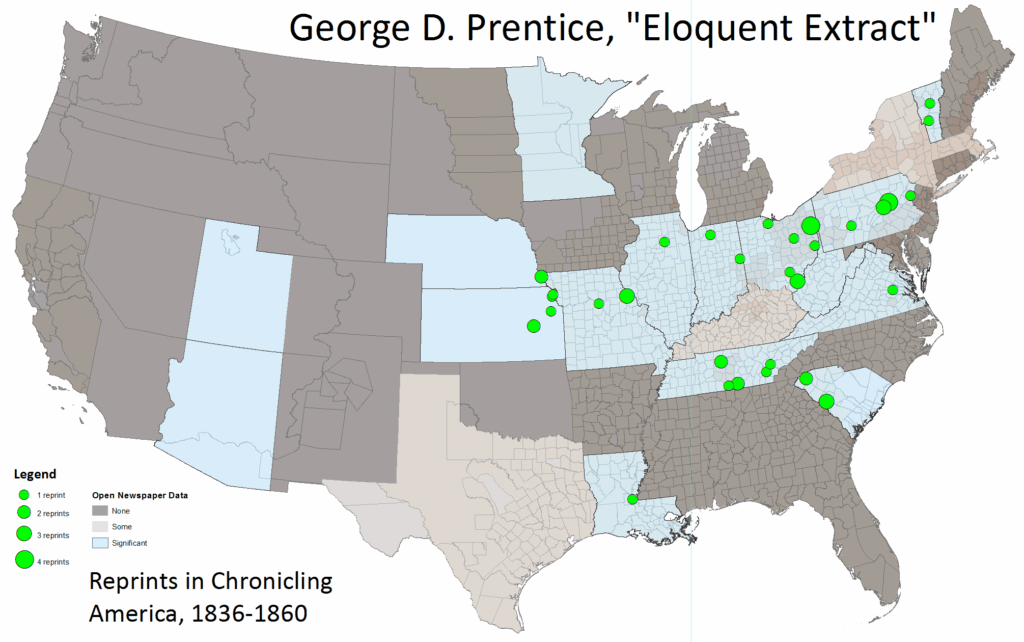
Output data and formats
The end result is comprised of many factors like publications, data visualizations, computational tools, theoretical models, and a general gain of knowledge.
The most important piece of knowledge gained is that such largescale data does not work. The amount of work it takes to gather, compute, and then turn into clean data is a very large work load.
Along with the searchable database, they have another page with all of their software data. The GitHub site shows trends and different sections within their research.
Connection to DH Best Practices
The whole website is broken down into smaller sections, but finding those sections is difficult. To get to the data page was a struggle, especially since it took a specific sequence of clicking on different drop down menus.
After navigating the maze, the pages themselves are clearly written and understandable. Their documentation is thorough but hard to find first try.