Data Description
The data consists of digitized habeas petitions, biographical information, and different legal locations
Majority of the data is displayed as chunks of text within the website, or images for very few entries such as the stories. This is for ease of access and reading for the every day person researching or viewing this website for fun.
The original documents, only some of which are linked to cases or people, are blurry and hard to read, but the project does have a section with instructions on how to look at original source materials
Input Data and Sources
In this project, data is a series of digital page images.
This project gathers its data from different locations depending on the type of information being catalogued. The physical case materials are found in the archives of different county, state, and federal courts. Those archives are then also catalogued and baseline information is provided about them
Information about individuals is found from books such as “History of Oregon, Volume 2”, census records, or in some cases newspaper articles about the person written while they were alive
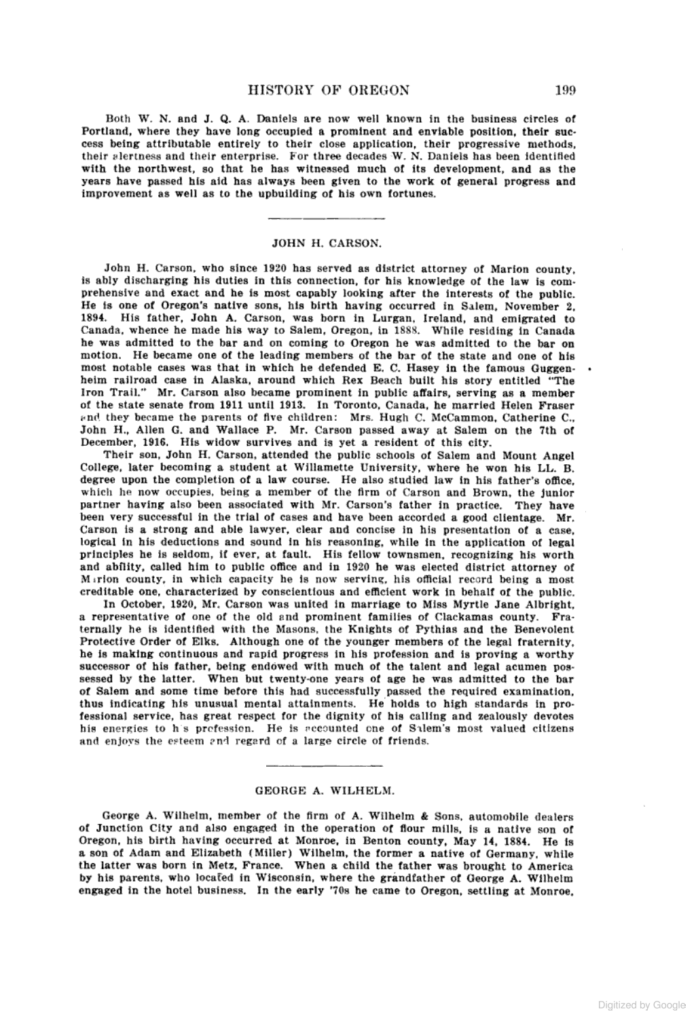

Images from “History of Oregon, Volume 2” which the project uses to collect data on individuals
Output Data and Formats
The end result is a web database that allows exploration through a searchable database.
“Petitioning for Freedom” consists of individual pages with carefully curated text written by researchers. Each page is home to a person, a case, or a location and all the possible information that could be gathered about them.
All of them link to other pages with relevant people involved in cases, locations where the case took place, and archives where information was gathered.

Screenshot of a completed webpage for reference
Despite the fact that very few of these pages contain any form of image, the digital data download is available in CSV or JSON formats.
Digital Humanities Best Practices: Documentation
The data collection does not follow best practices for documentation.
The team behind PFF did not document the process of accessing their sources or have an easily accessible data download. A data download is available through GitHub, but it’s not easy for the average person to understand or access.
In terms of the people documented on project website itself, source of where information was gathered is listed on a person’s individual page
Cases list the repository where the information was pulled from, and a blurb on how to access the complete case file if anyone is interested.
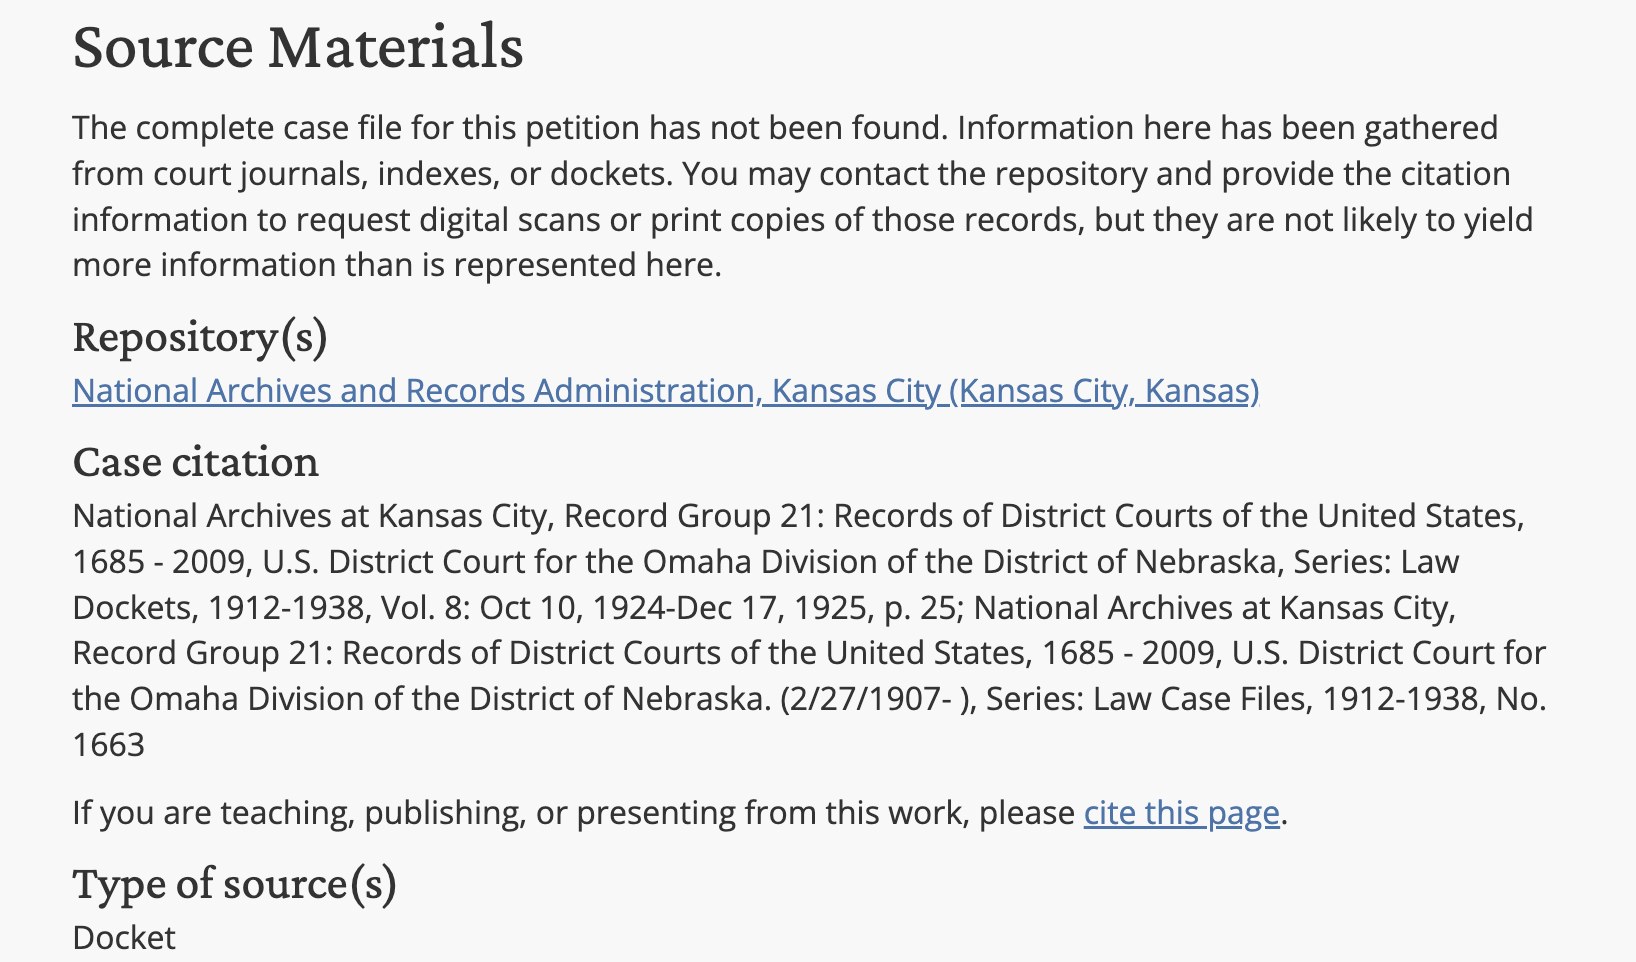
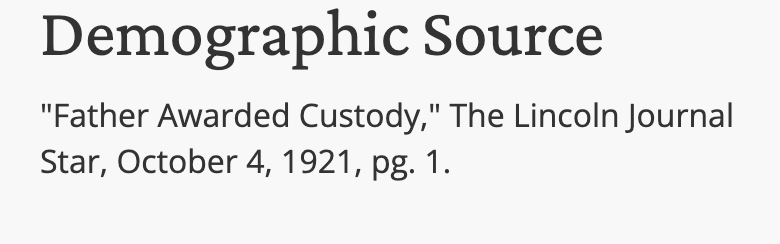
Screenshots of source information gathered from individual pages
Sources are linked when possible, but sometimes they’re just listed with written word