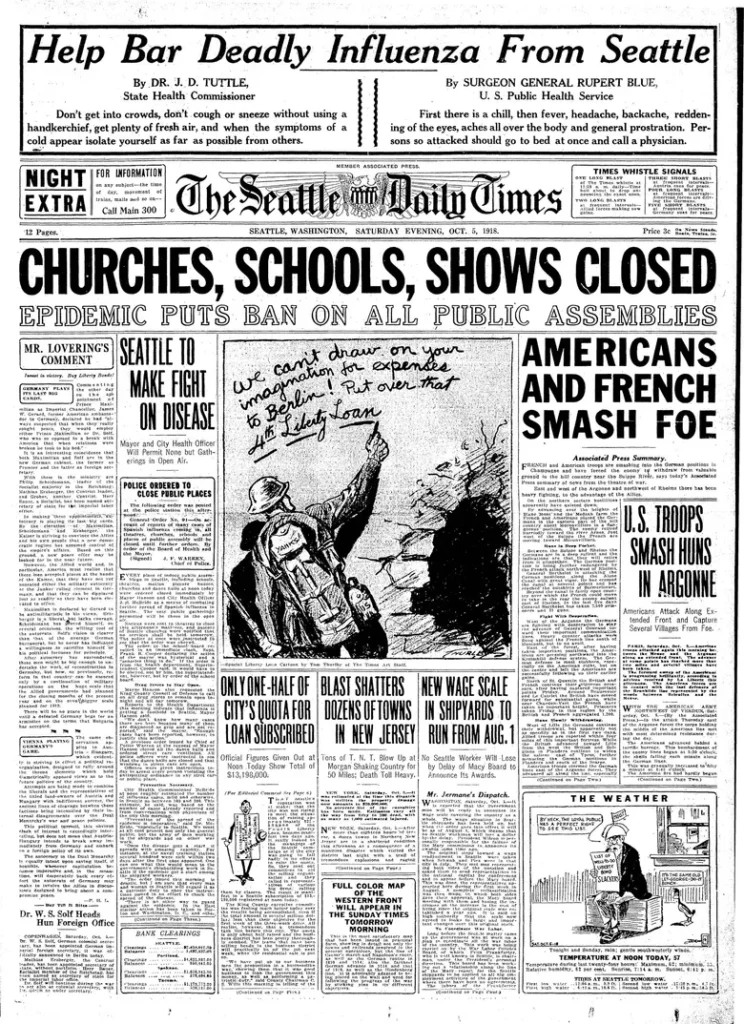
Newspaper articles were used to help understand the public health crisis using data mining techniques by exploring newspaper article headers. This Digging into Data project was to complement open-access historical newspapers from the U.S. and Canada with historical newspaper digital archives already available on campus under the Virginia Tech Libraries’ licenses. They also found that its sources such as the Chronicling America collection, present significant limitations to estimate based research and data mining cannot substitute for close or “manual” readings of discrete texts.
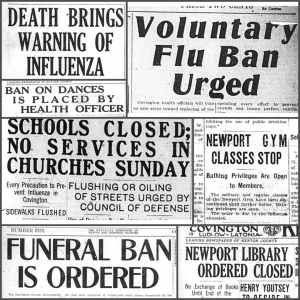
-examples below of some newspaper article headings.
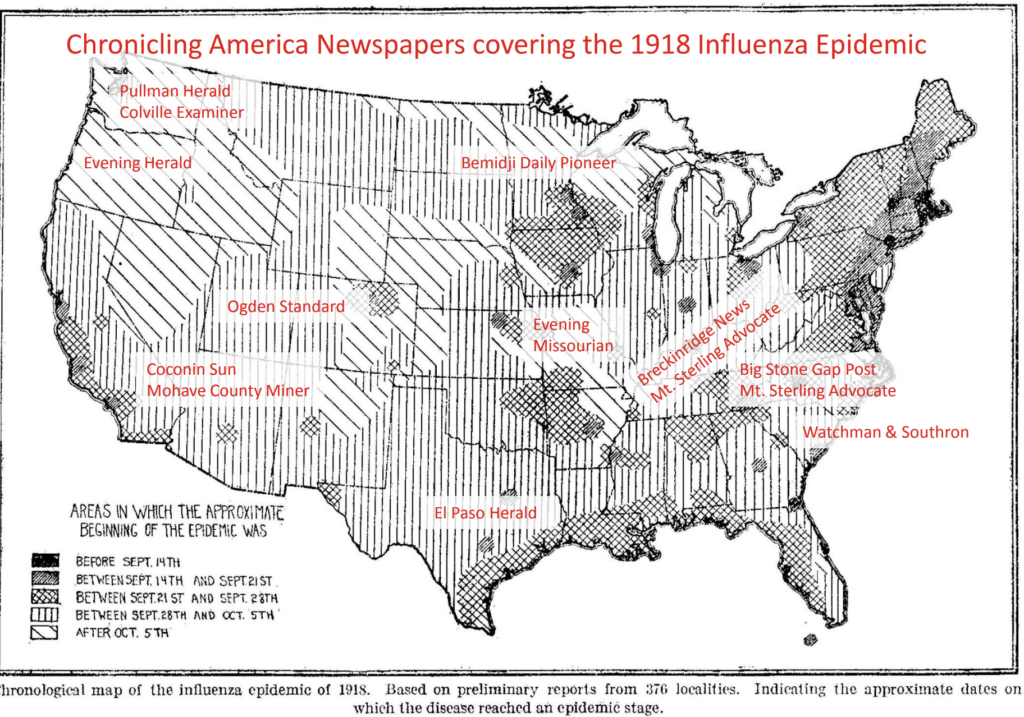
With this project they are four different case studies first Weekly Newspaper Case Study; The combined methods used in this project were used to review weekly newspapers illustrates both the richness of information about influenza contained in weekly newspapers and the complexity of analyzing textual materials using automated analysis. This case study demonstrates the complex information networks that functioned through newspapers and suggests the value of our methods for contemporary contexts
Next, Daily Newspaper Case Study; The most important findings of this study involve the difference that scale makes in analyzing data mining outputs of news reporting. The outputs for all the papers together significantly differ from the outputs for the individual papers.
Third, Vaccination-Visualization Case Study; Visualizations, as ways of rendering data mining outputs, are rhetorical and require tacit knowledge. The process of research and interpretations of data outputs are affected by various forms of visualization as well as by the data input conventions underlying the algorithms. (Next page is a ThemeDelta visualization, which is a great example for this case study)
Last, Public Health Officals Case Study; By identifying proximity of medical terms, public health responses, and broad statements of impact, topic modeling and segmentation quickly identify word associations that are suggestive of broader interpretations.