Tools
EarlyPrint uses a variety of digital tools and software to power its database, including:
- BlackLab: a search tool used for finding keywords or sequences within a large corpus of data
- XML: Extensible Markup Language (XML) is used for structured and hierarchical management of metadata
EarlyPrint’s search and analysis tools are powered by MorphAdorner, a Java-based software package designed for processing large data sets which “tokenizes text, regularizes the spelling of each word, lemmatizes it, assesses its syntax and assigns it a part of speech tag.” Developed specifically for humanities scholars seeking to conduct literary and linguistical analysis, MorphAdorner “adorns” or adds to the textual data in EarlyPrint by:
- Tokenization: splitting lines of text into discrete “tokens,” such as individual words and spaces to streamline machine reading (i.e., “I dream of plants” becomes “I,” “dream,” “of,” “plants”)
- Markup: affixing specific tags to various textual features such as linguistical categories, variant spellings of words with regularized forms, punctuation, and syntactical variations (i.e., “prynted” read and tagged as “printed”)
- Distinguishing boundaries between words, sentences, line breaks, and punctuation to assist machine reading (i.e., “to morrow” read as one word instead of two)
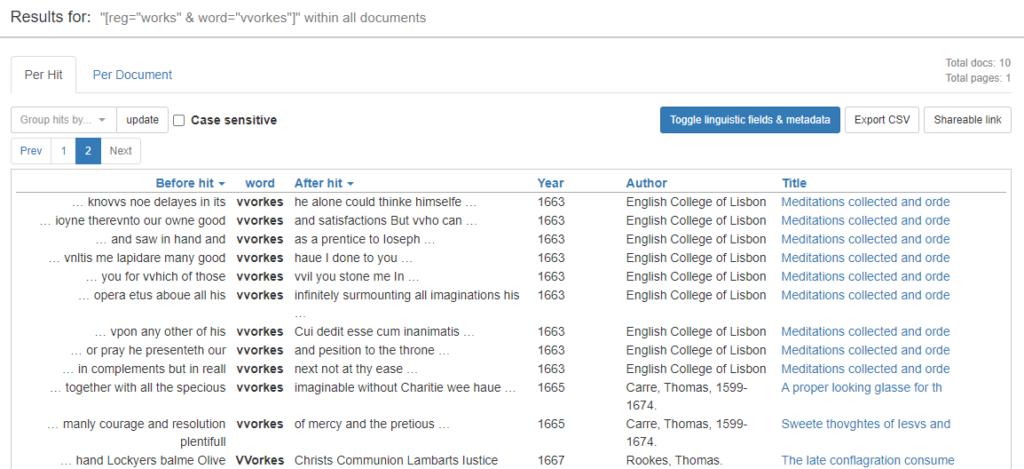
The MorphAdorner software is free to download from its website, which also features extensive documentation on how to use it. EarlyPrint also features a page which explains the implementation of the software within the project. Thus, the use of a well-documented and openly accessible software aligns with the best practices of DH. Below is an example of using MorphAdorner to search for texts with “vvorkes,” an alternate spelling of “works.”