The data in Photo grammar is mainly made up of:
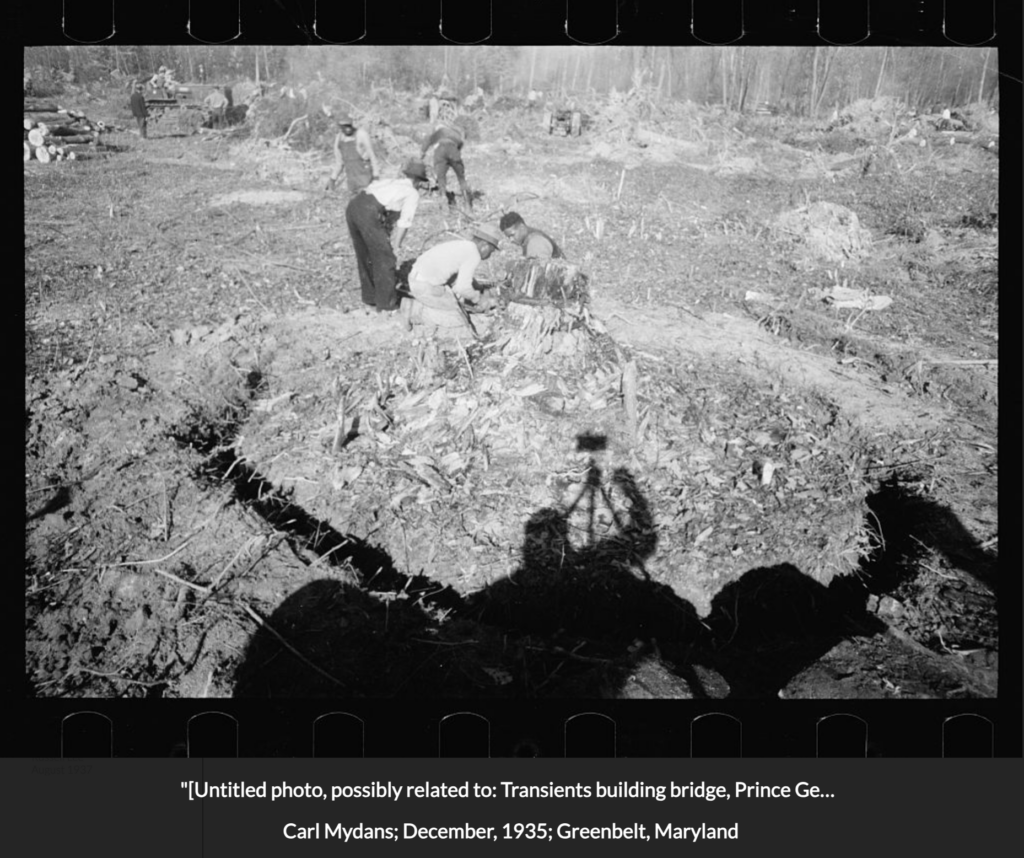
- Historical photographs
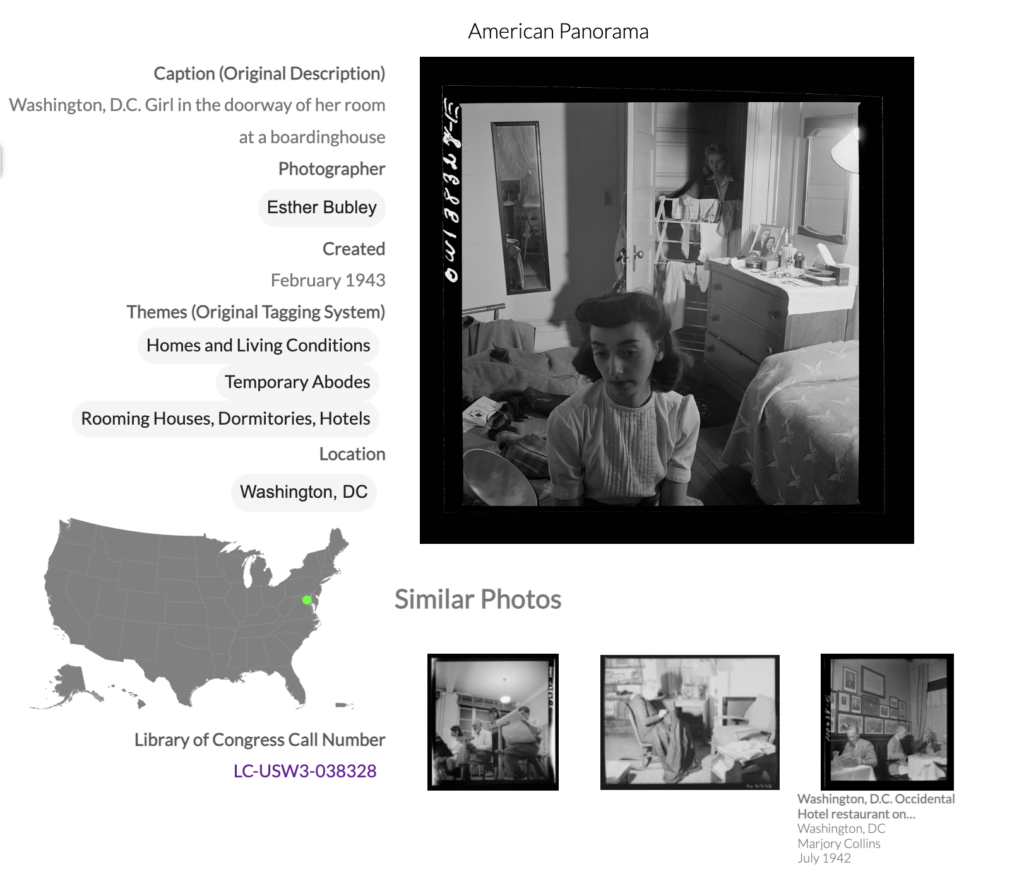
- Information about those photos (metadata), like date, location, and photographer
Type of Format Data
- Image files (the photos themselves)
- Structured data (organized metadata)
- Geographic data (used for maps)
Input Data and Sources
The project starts with photographs from the Farm Security Administration and Office of War Information, which are stored in the Library of Congress.
- What: Historical photos + metadata
- Where from: Library of Congress archives
This data was hard to explore, which is why this project reorganizes it.
Output Data and Format
Photo grammar turns that raw data into:
- Interactive maps
- Searchable databases
- Visual tools like charts and categories
End Result
The final result is a website where users can explore history in a much more interactive way. Instead of just looking at photos, they can actually analyze trends and patterns.
Also most of the data is publicly available, and many of the images are in the public domain. This is important because it allows other people to use the data for research or learning.