The data that the team collected is from both textual and thematic. The first phase of the project’s data are from reprints from the nineteenth century in the United States. Also for the 2nd phase, the data was from the algorithm from the United States, United Kingdom, and Australia.
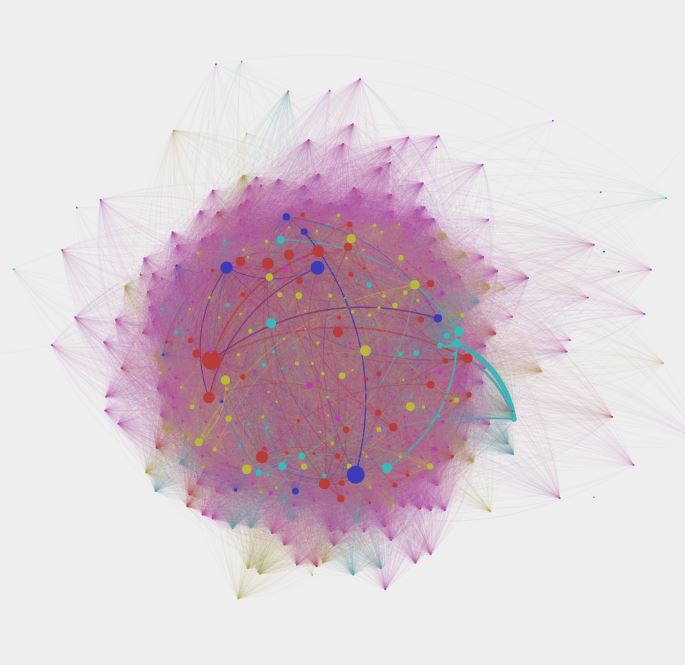
The graph here illustrates the connections for the newspapers with pre-civil-war content. While the circles/nodes represent individual newspapers, and the lines represent shared texts discovered by researchers working with the Viral Texts project.