This project is an important dataset for Digital Humanities. The dataset measures what physical libraries have collected overtime and has curated a list of novels based on actual holdings rather than basing it on online popularity. The novels are determined the “greatest” by which ones are most commonly found in libraries. By excluding digital books, it focuses on modern popularity as well as the history behind each libraries curation.
This project is significant to the area of study for social media as well. When gathering data, the platform “Goodreads” was used. Using Goodreads allowed the researchers to understand popularity and the biases it created.
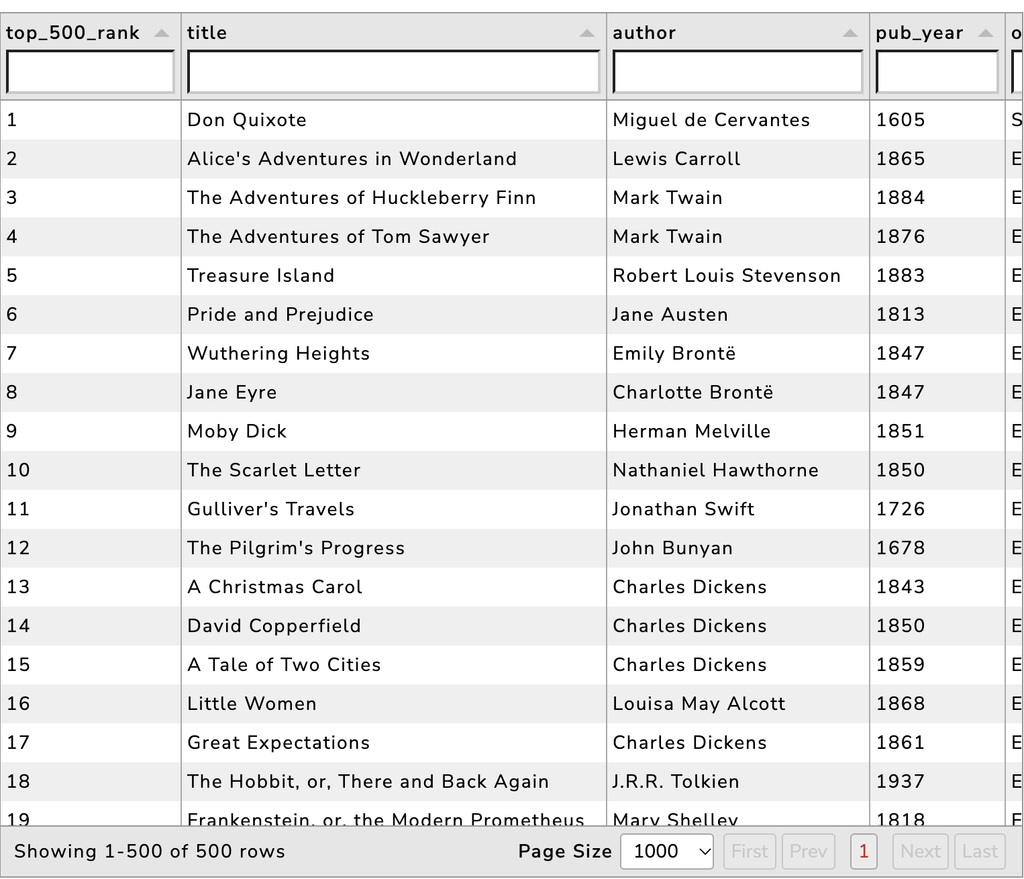
What is this project?
Who? What?
This is a dataset that contains information about the top 500 novels that are found most frequently in libraries. The authors of the digital project are Anna Preus and Aashna Sheth, but the list was collected by a team at OCLC (a global library organization), which is a non-profit organization. It was created using data compiled by librarians at the OCLC. The information given includes author’s biographies, online engagement for each novel, and library holdings. It also includes, for the novels that aren’t under copyright, the full text.
Where? When?
The Top 500 “Greatest” Novels project was published on July 1, 2024. There isn’t an exact “where” for the creation of this project. The OCLC is where the data came from. It’s taking data from many libraries in different countries. The United States, Germany, Australia, and Canada are some of these countries. The authors of the project, Anna Preus and Aashna Sheth, were both working at the University of Washington making this project.
Who’s the audience?
The audience for this project is for libraries, scholars, and novel lovers This data set allows access for many full texts and also allows for discussion amongst users. Furthermore, it’s quick access to information about classic novels.